A real, attributed dataset
A selected VisA subset from Amazon Science. Separate reference, calibration and holdout splits. Dataset labels remain separate from model outputs.
Dataset & CC BY 4.0 licenseA visual inspection lab
A useful classifier needs more than a prediction. Inspect real photographs, tune the review threshold, and see exactly where AI gets it wrong.
Explore the labReal photos. Real model estimates.
Clear, flag, or ask for human review.
Two policies. One held-out test set.
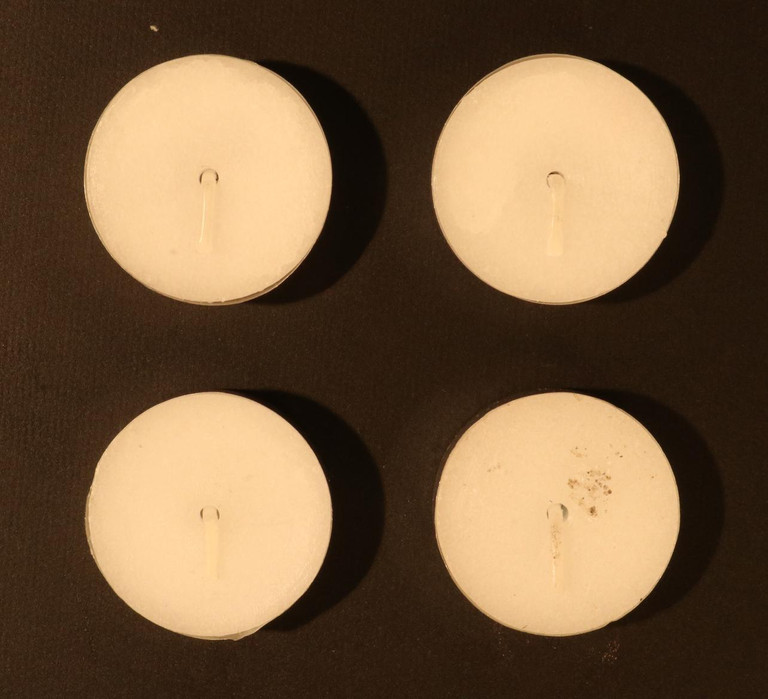 Original photograph
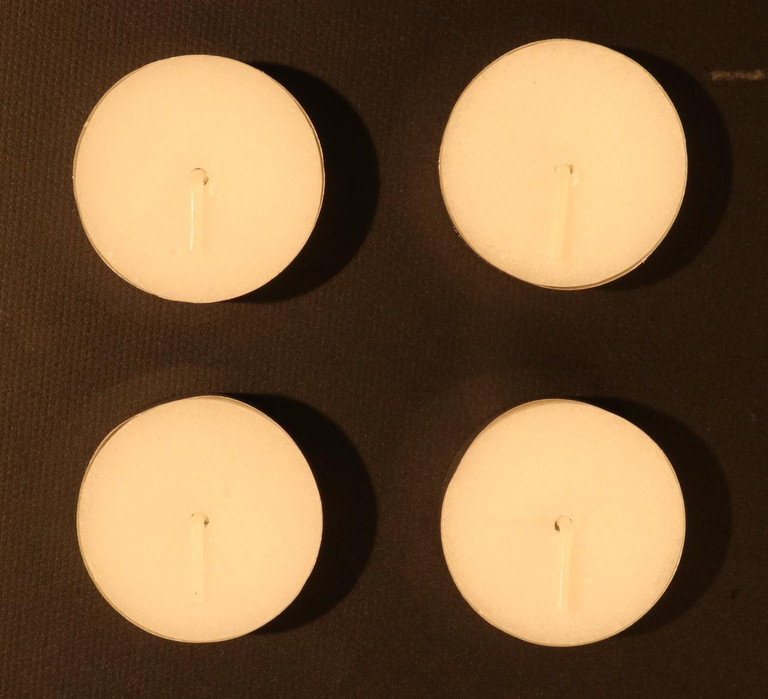
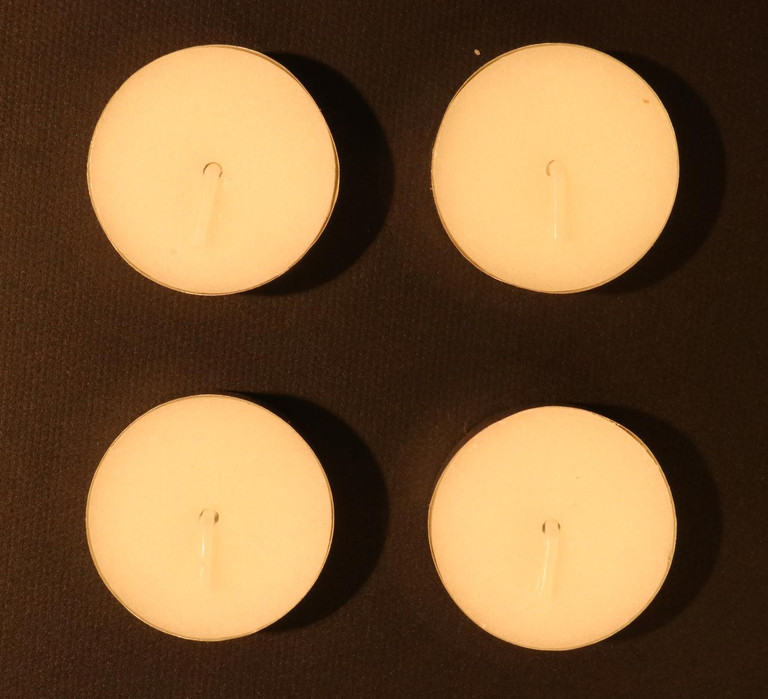
Separate reference photos. Never included in calibration or holdout metrics.
The estimated anomaly probability is at or above the flag threshold.
Model estimates, not calibrated certainty. Severity describes visible appearance only.
Severity distribution (none / subtle / clear / extensive): 0.0% · 0.0% · 100.0% · 0.0%
Your label is kept separately. It does not change dataset truth or retrain the model.
A clear result means no visible anomaly was detected under this policy. It does not certify function or safety.
Built for scrutiny
A selected VisA subset from Amazon Science. Separate reference, calibration and holdout splits. Dataset labels remain separate from model outputs.
Dataset & CC BY 4.0 licenseOpenAI Decisions estimates anomaly and usability probabilities, identifies the product family, and scores visible severity. Code applies the routing rules.
Explore the APIHuman corrections are review records, not automatic retraining. Saved API results are labelled. Live uploads remain in memory, with no demo-side image storage.
Read the implementationWe turn a specific operational problem into working software, with clear evidence of where AI helps and where a person still belongs.